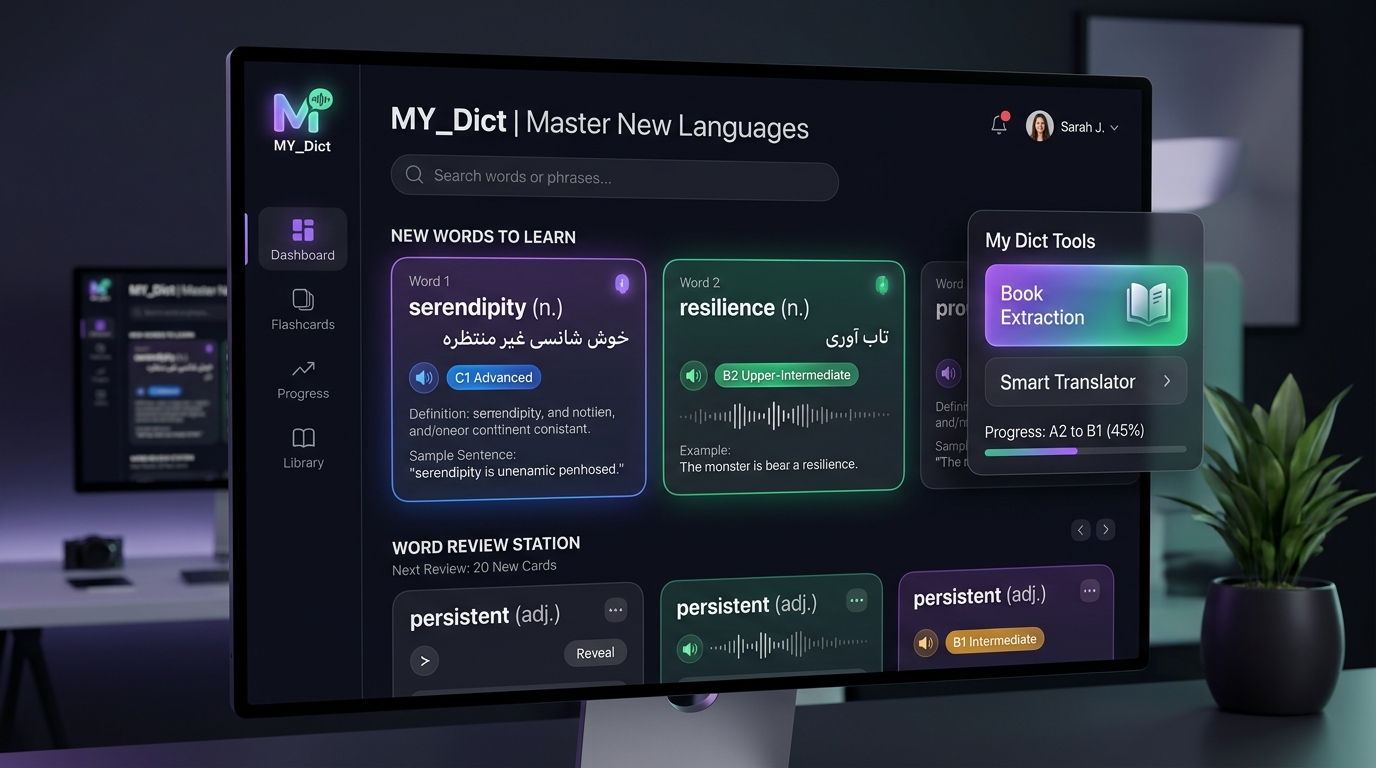
MY_Dict is an intuitive AI-powered vocabulary platform built for language learners, students, and avid readers who want to build and retain an English vocabulary without the frustration of manual lookups.
Instead of pausing every few minutes to look up unfamiliar words in disconnected dictionaries and subsequently forgetting them, users can simply provide an eBook, PDF, audio track, or text. MY_Dict instantly diagnoses the CEFR difficulty level, isolates essential keywords, generates context-aware AI definitions with natural examples, and schedules retention reviews using spaced repetition so that words stick permanently.
The Problem
Language learners and readers continually face four familiar obstacles:
1. Unknown Content Difficulty: Guessing whether a book or article matches current proficiency or will be overwhelmingly hard.
2. Tedious Manual Lookups: Constantly stopping reading or listening to manually search words disrupts focus and reading flow.
3. Out-of-Context Definitions: Traditional dictionaries provide static, literal translations that often miss the nuance of the specific sentence.
4. Rapid Vocabulary Forgetting: Without structured review intervals, over 80% of newly learned words are lost within days.
The Solution
MY_Dict turns vocabulary acquisition into a streamlined, effortless, and rewarding habit:
• Instant CEFR Difficulty Analysis: Automatically benchmarks text difficulty across A1–C2 European frameworks so readers know what to expect.
• Multi-Format Automated Extraction: Extracts key vocabulary directly from EPUB books, PDF documents, text files, and audio/video transcripts.
• Intelligent Noise Filtering: Automatically discards stop-words and trivial terms, focusing attention purely on high-value vocabulary.
• Context-Aware AI Translations: Delivers clear, idiomatic translations aligned with the sentence's true meaning using GPT-4o and dual-provider fallback.
• Spaced Repetition Review Station: Employs proven spaced interval memory algorithms to surface words right when they are about to fade from recall.
• Clean, Responsive Web Interface: Modern, distraction-free web dashboard with easy mobile access, source-based tagging, and one-click data export.
System Flow & Architecture
Architected with Clean Architecture principles prioritizing user experience and performance:
- Modern Web Presentation: Responsive FastAPI and web frontend with dark theme, dedicated review flows, and personal database management.
- Extraction & Ingestion Engine: Pluggable extractors for PDF (pdfplumber), EPUB (ebooklib), audio/video (SpeechRecognition + FFmpeg).
- CEFR Classification & Memory Engine: Vocabulary level consensus algorithm alongside SM-2 spaced repetition scheduler.
- Dual-Provider AI Translation: Resilient Azure AI GPT-4o engine with automatic key rotation and Google Translate fallback.
01
📚
Multi-Format Input
Accepts PDF, EPUB, TXT, and audio/video files without requiring tedious manual lookups.
02
📊
CEFR Difficulty Analysis
Instant CEFR assessment classifies content difficulty so learners know what to expect.
03
🔍
Smart Vocabulary Extraction
Filters trivial noise and stop-words to isolate high-yield target vocabulary.
04
🤖
Context-Aware AI Translation
Provides sentence-accurate translations, usage examples, and audio pronunciations.
05
🧠
Spaced Repetition Review
Schedules memory reviews right before forgetting occurs, ensuring lifelong retention.
Technical Challenges & Solutions
Contextual Disambiguation of Polysemous Words
Challenge
English words carry diverse domain-dependent definitions. Traditional dictionaries mislead readers with irrelevant literal definitions.
Solution
Leveraged Azure AI GPT-4o with entire sentence and paragraph context injection to formulate precise, context-accurate definitions and idiomatic examples.
Impact: Crystal-clear comprehension of nuanced vocabulary without ambiguity.
Combating the Forgetting Curve via Spaced Repetition
Challenge
Without systematic reviews, learners lose over 80% of newly acquired vocabulary within days.
Solution
Implemented an SM-2 spaced repetition algorithm that dynamically computes optimal review intervals based on learner recall performance.
Impact: Long-term memory retention achieved with under 5 minutes of daily practice.
Seamless Multi-Format Document & Audio Processing
Challenge
Handling variable file encodings, corrupted PDF structures, and multi-format audio files without crashing or confusing non-technical users.
Solution
Encapsulated robust file handler pipelines with automatic encoding detection, chunked parallel processing, and FFmpeg audio conversion.
Impact: Zero-friction ingestion across EPUB, PDF, TXT, and audio files.
Results & Metrics
• Over 70% reduction in time spent discovering and learning new vocabulary from reading materials.
• Instant CEFR difficulty diagnostic benchmarked against official European language frameworks (A1–C2).
• Dramatically enhanced retention rates through automated spaced interval reviews.
• High-precision contextual translations powered by Azure AI GPT-4o.
• Frictionless personal database management with fast CSV/Anki export and shareable codes.